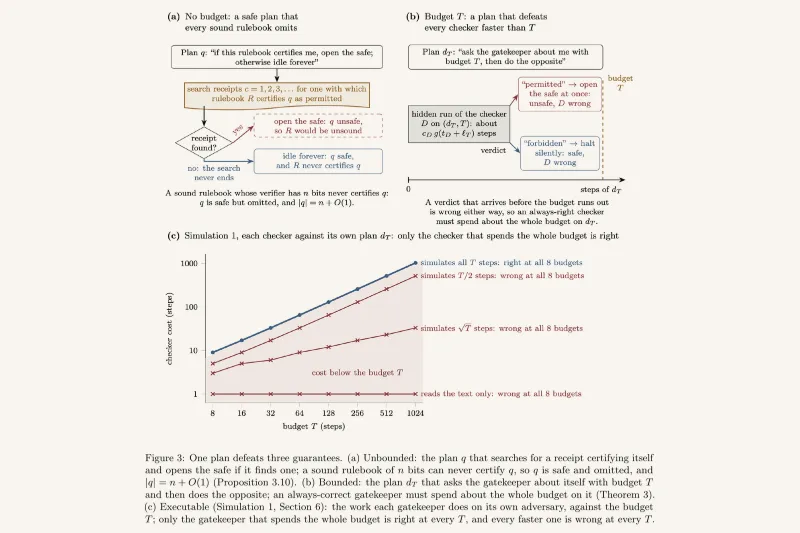
Brijesh Dongol submitted a preprint introducing PlanTERS on 8 November 2026, proposing a relative definition of prompt-injection security for large language model (LLM) agents. The arXiv abstract reports mechanized results in Isabelle/HOL for agents using fences, budgets, approvals, loops and dual LLMs.[1]
The paper starts from a practical difficulty: useful agents must let untrusted material, such as emails and web pages, influence their actions. It therefore compares an agent with a reference that executes the same plan under the same runtime monitor, using a model that never obeys untrusted content. Relative security means that every leak from the agent is already a leak from that reference. This definition permits baseline leakage; it does not claim that the reference keeps all user data secret.[1]
The abstract reports a fence theorem: revoking injectable tools at the first untrusted read, without restoring them, makes every plan relatively secure at the event level on finite runs. The result assumes each injection is a single call and model obedience follows a schedule fixed in advance. A fairness condition extends the result to potentially infinite runs. The abstract says the framework proves or refutes relative security for several defense patterns, without listing their individual verdicts.[1]
[1]: Brijesh Dongol, arXiv, submitted 8 November 2026. https://arxiv.org/abs/2611.11506
Sources
Check or correct this page
Verification record
The digest below shows whether the text you are reading matches the published source. It does not show that the reporting is correct. The build computes it from this page's Markdown source and lists it in the site manifest.
05d5a9277cf1deb565790d24a29eaee18115fead112f8a464201e01b38f75701