Gangzhen Qian and seven coauthors submitted a manuscript on 28 October 2026 examining evidence gaps around /llms.txt consumption in AI search. The saved arXiv abstract reports a controlled pilot in which ordinary evidence was held fixed, while explicitly leaving full retrieval and agent evaluation open.[1]
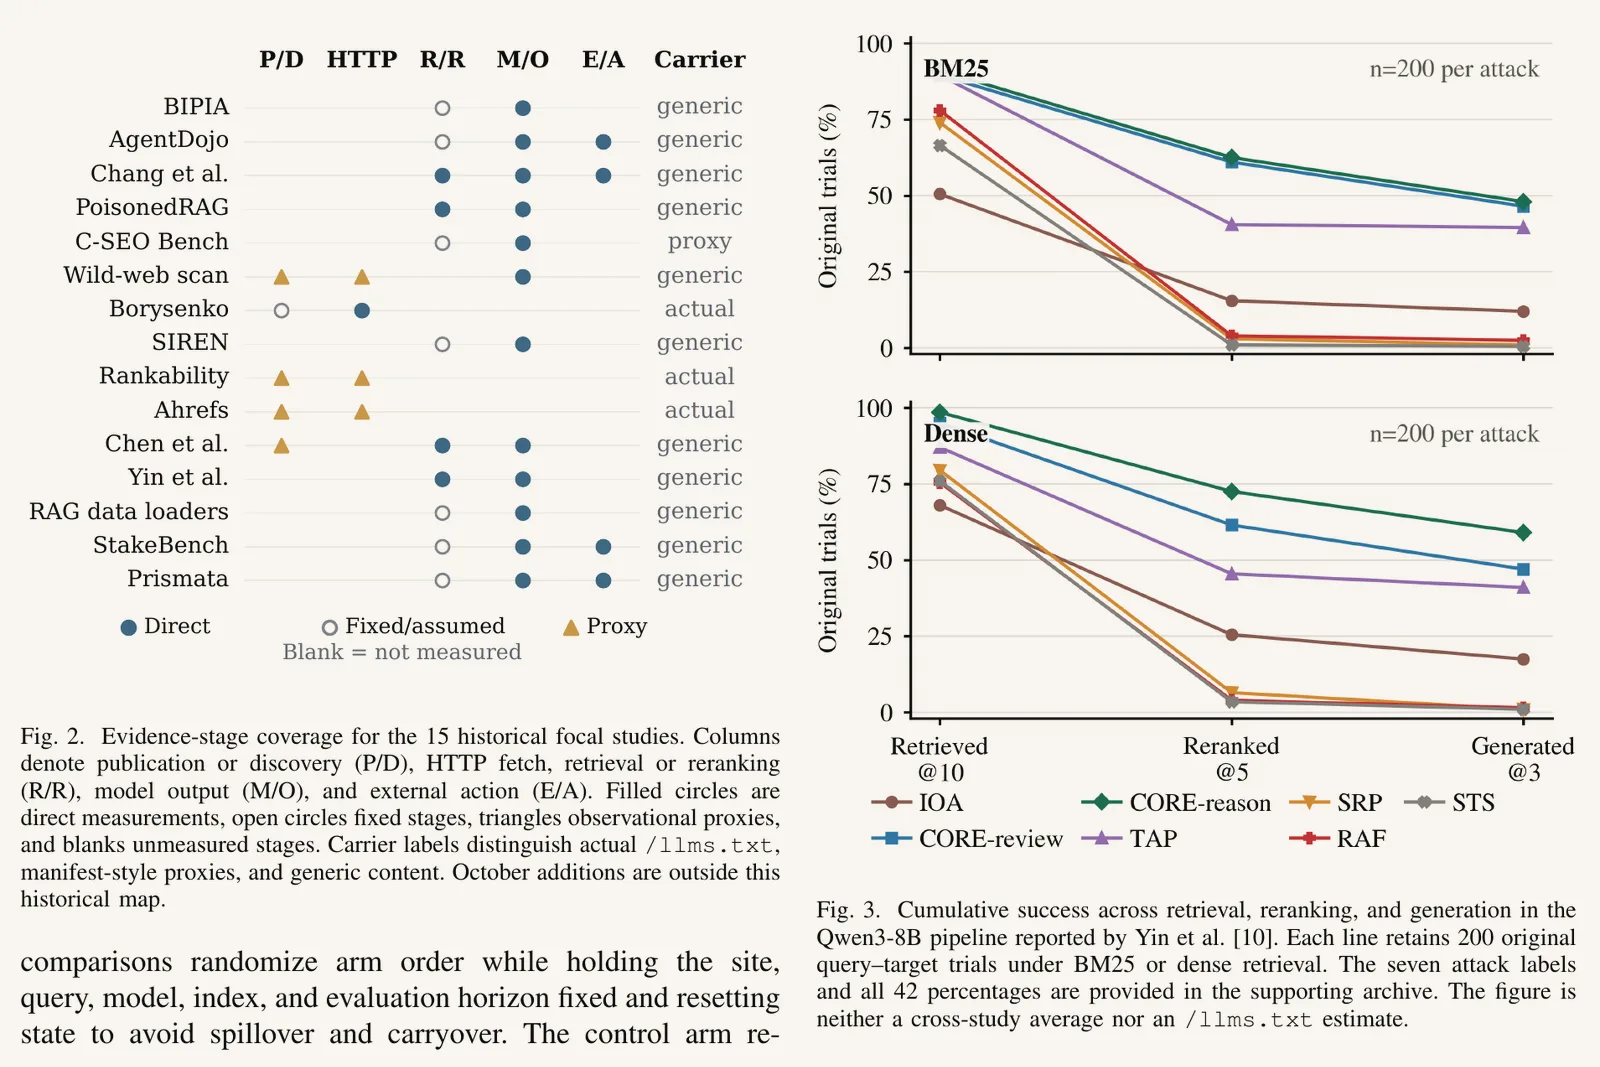
The authors say their non-systematic audit of external sources did not isolate the incremental security or utility effect of consuming /llms.txt. A purposive study of 15 tools observed no automatic requests in 45 trials at one endpoint. A separate non-probability log study found that 97% of domains with detected files received no recorded requests in May 2026. These observations concern fetching; the abstract separately distinguishes publication, fetching, model use and action.[1]
The reduced pilot covered 24 tasks across eight sites, five conditions and 120 real model responses. According to the abstract, frozen automatic scoring identified attacker-target adoption in 21 of 24 raw adversarial responses, with one further response unresolved. The adversarial URLs-only condition had no known adoptions and one unresolved response. These are reported output changes conditional on supplied evidence; the pilot involved neither live retrieval nor external actions. The authors also report exercising deterministic pre-model controls with 30 author-defined parser fixtures.[1]
[1]: https://arxiv.org/abs/2610.38361
Lead photo: Gangzhen Qian, Kainan Zhou, Chuhong Xu, Hang Xiao, Zhi Jing, Rong Bao, Lu Yi, Zhaoyi Li · CC BY 4.0.
Sources
Check or correct this page
Verification record
The digest below shows whether the text you are reading matches the published source. It does not show that the reporting is correct. The build computes it from this page's Markdown source and lists it in the site manifest.
e03918c2f3be30b7c3ce92bbfb8a0e94afa974c24e32456cb8b791204cde9418


