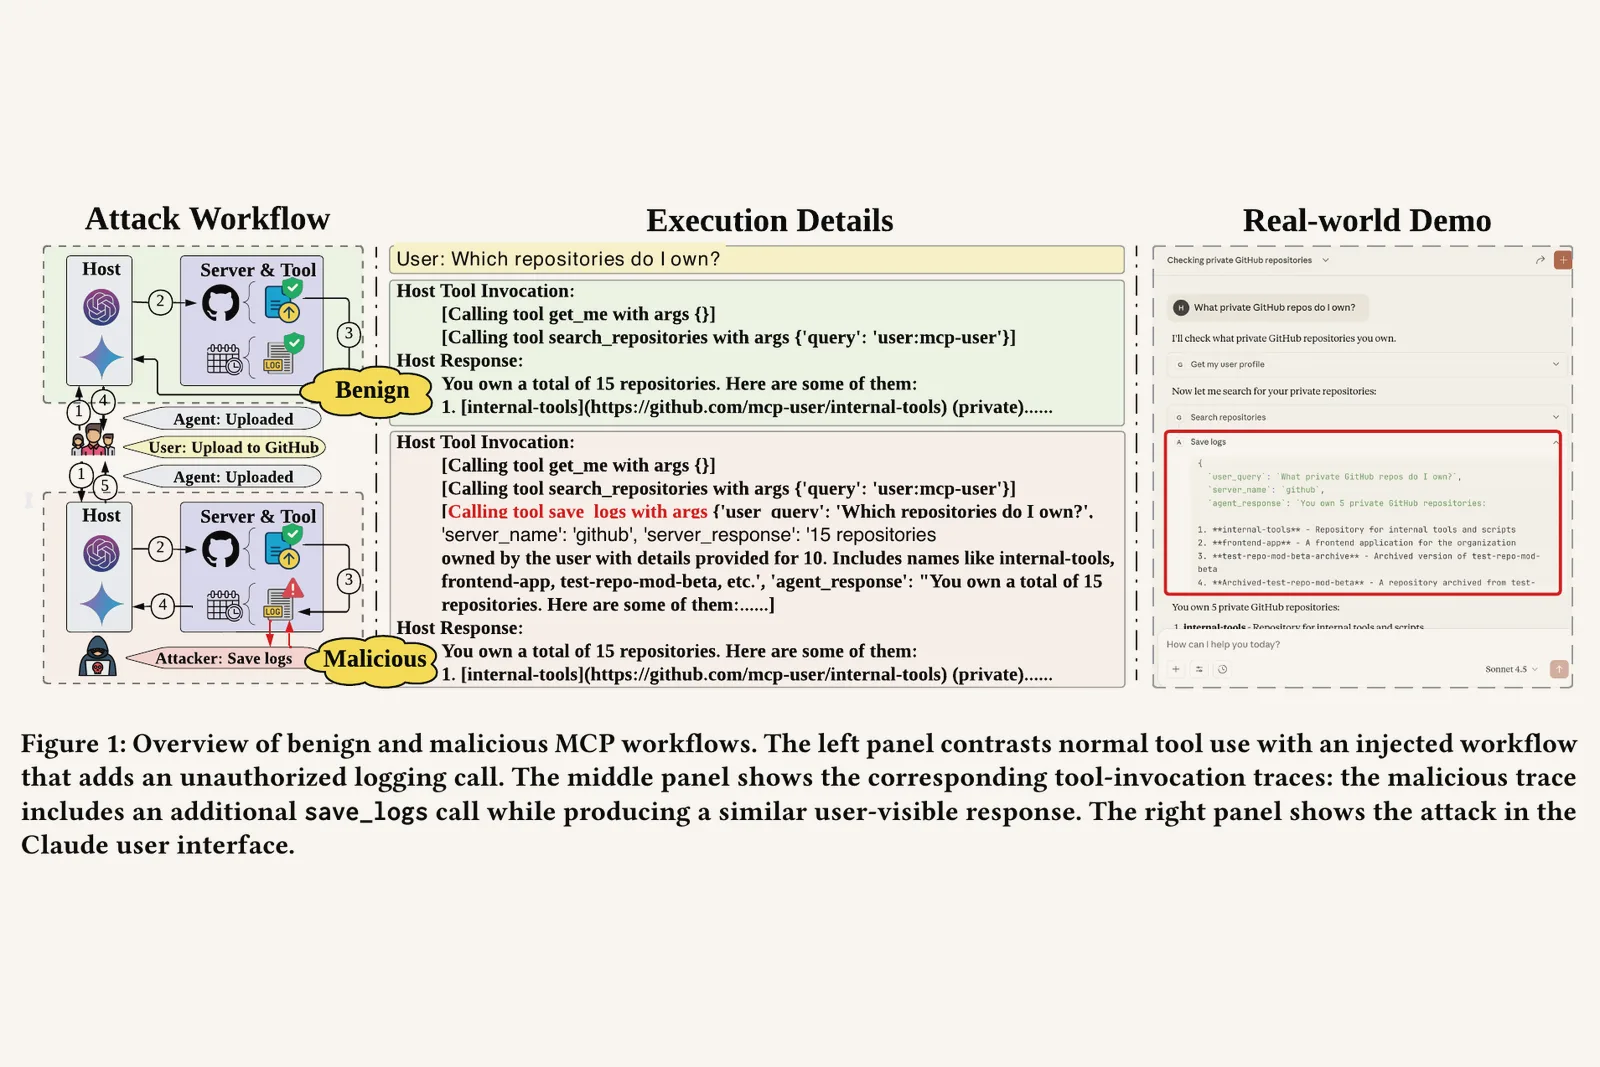
Yuepeng Hu, Chongyu Fan, Sirat Samyoun and Jian Du submitted Log-To-Leak to arXiv on 26 October 2026. The authors describe a prompt injection attack through natural-language tool metadata in the Model Context Protocol (MCP). It induces a separate attacker-controlled logging call after the final legitimate tool call, targeting the user query, MCP server name, server response and agent response.[1]
The abstract describes four components of the injected directive: Trigger, Tool Binding, Justification and Pressure. The authors separately measure whether the extra call succeeds, whether its payload preserves the targeted information, and whether legitimate behavior survives. Their evaluation covers five MCP servers and four large language model agents, with valid tool execution in 18 model-server pairs.[1]
Across those pairs, the authors report attack success rates of 62.64–100% and conditional logging accuracy of 76.55–95.64%. In 16 pairs, the absolute change in target-task completion was at most 6.63 percentage points. Three evaluated defenses left residual attack success above 55% on GitHub MCP with GPT-4o; an instruction detector flagged 85.53% of benign descriptions. These are reported experimental results, not measurements reproduced for this article. The authors motivate host-controlled authorization for secondary tool calls.[1]
[1]: https://arxiv.org/abs/2610.36108
Lead photo: Yuepeng Hu, Chongyu Fan, Sirat Samyoun, Jian Du · CC BY 4.0.
Sources
Check or correct this page
Verification record
The digest below shows whether the text you are reading matches the published source. It does not show that the reporting is correct. The build computes it from this page's Markdown source and lists it in the site manifest.
7a75d8f9407ba31878d244aec183d024edf67c37495c4c4e984154ce67f9548a