Doron Shavit submitted a paper to arXiv on 8 November 2026 proposing a runtime audit for tool-using agents exposed to indirect prompt injection: instructions hidden in tool outputs that steer an agent toward actions the user did not request. The abstract describes a way to check tool calls against the user's objective, but explicitly says end-to-end validation remains open.[1]
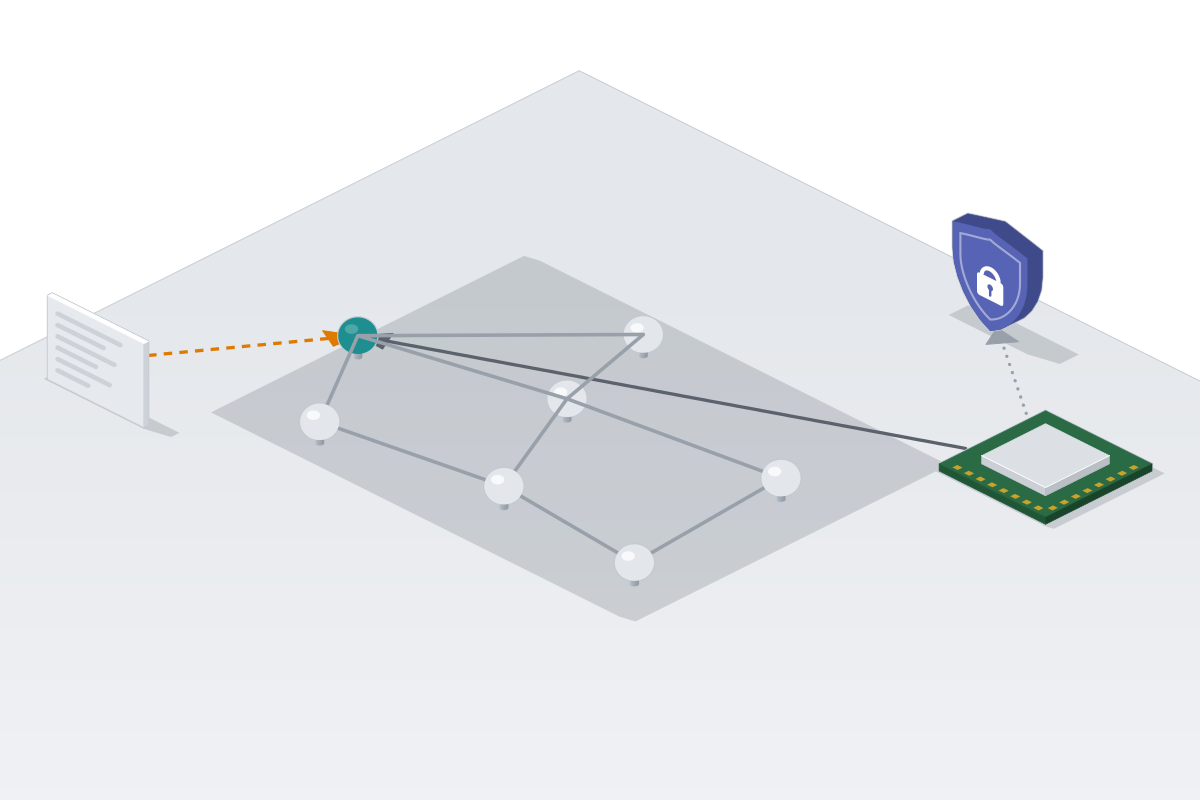
The proposed audit uses one large language model (LLM) call per task to derive an executable intent graph from the objective and the deployment's tool catalog. A deterministic loop then checks each tool call against that graph without additional LLM calls. The abstract reports a median of 5.7 microseconds per call; that is the author's reported measurement, which we have not reproduced.[1]
Two mechanisms aim to recover utility. Lookups of the user's own state bypass the audit, based on the author's rationale that an attack's harm lies in its write or outward step. Remaining flagged calls go to a reasoning guardian. It receives the objective, plan, call history without tool outputs, and flagged call, and can check facts using a restricted Python-expression tool. The abstract also says a current agent showed no baseline attack success, leaving the proposed defense's end-to-end validation unresolved.[1]
[1]: https://arxiv.org/abs/2611.11305
Sources
Check or correct this page
Verification record
The digest below shows whether the text you are reading matches the published source. It does not show that the reporting is correct. The build computes it from this page's Markdown source and lists it in the site manifest.
d81b7e2a5c27039a690b906c8c6cb6e3676ad6978ab0cad7e1d33705e7edcd7c


